My practical 2026 take:
Iceberg for openness.
Delta for Databricks depth.
Hudi for CDC-heavy mutability.
Full breakdown: medium.com/@sriwworldof...

 @sriwworldofcoding.bsky.social
My practical 2026 take:
Iceberg for openness.
Delta for Databricks depth.
Hudi for CDC-heavy mutability.
Full breakdown: medium.com/@sriwworldof...
 @nicolauroca.bsky.social
La opción de cambiar de plataforma envejece si nunca se revisa. Una función nueva o un consumidor adicional puede alterar lo que antes era portable. Conservar la salida exige mantener vigente su evidencia.
 @sriwworldofcoding.bsky.social
Choosing Iceberg, Delta, or Hudi based on hype is how teams create expensive data-platform regrets.
Choose based on workload:
Iceberg → multi-engine
Delta → Databricks/Spark
Hudi → CDC and upsert
The “best” format is the one your architecture can live with.
#Bigdata #ApacheIceberg #DeltaLake
 @vyruss.org
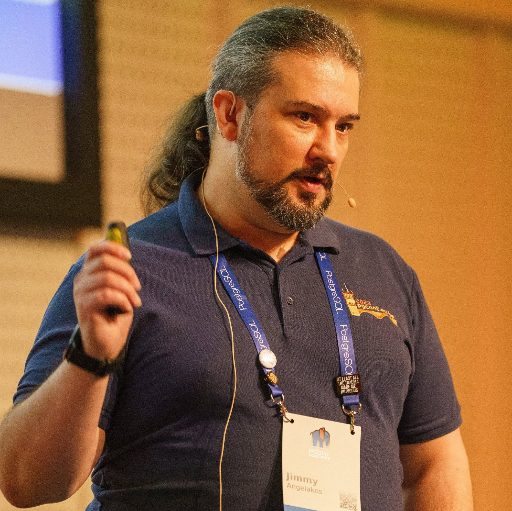
Christian Thiel (Vakamo) "A Year at REST: What’s New in Iceberg REST Catalogs" at #Apache Community Over Code #Lakehouse Day 2026 in #Glasgow
 @sriwworldofcoding.bsky.social
The best format is not “the most popular one.”
It is the one that fits your engines, catalog, latency needs, and team operations.
Read the beginner guide:
medium.com/@sriwworldof...
@sriwworldofcoding.bsky.socialA folder of Parquet files is not a table.
It is just storage.
Apache Iceberg, Delta Lake, and Hudi turn that storage into a transactional, versioned, queryable data lakehouse table.
Link : medium.com/@sriwworldof...
@sriwworldofcoding.bsky.socialI wrote a detailed breakdown of Apache Iceberg covering the architecture, problems it solves, time travel, practical concepts and interview perspective.
Read the full article : medium.com/@sriwworldof...
Follow for more Data Engineering content.
@sriwworldofcoding.bsky.socialTransactions + schema evolution + time travel + reliable tables.
The “just store Parquet files in S3” era has evolved.
 @pgedge.bsky.social
Tonight at the London PostgreSQL meetup, pgEdge's Jimmy Angelakos presents ColdFront (public beta): data tiering to Apache Iceberg on S3, same SQL, writable cold tier. 20:15, registration required: 🎙️ www.meetup.com/london-postg... #PostgreSQL #ApacheIceberg
 @nicolauroca.bsky.social
Una transformación que depende de una función del motor puede seguir atada a él aunque la tabla sea Iceberg. La pregunta útil es qué cálculo habría que reconstruir: ahí se concreta el coste de cambiar.
 @vyruss.org
This Thursday (Oct 8th) I'm speaking at the Iceberg Europe Community #Meetup in #London! I'll present 🐘🧊 #ColdFront: transparent #Postgres data tiering to Apache Iceberg for the modern #Lakehouse. Come say hi! Or join online.
RSVP: luma.com/ogtqk9eh
 @vyruss.org
This Wednesday (Oct 7th) I'm speaking at the #London #PostgreSQL #Meetup! I'll present 🐘🧊 #ColdFront: transparent #Postgres data tiering to Apache Iceberg for the modern #Lakehouse. Hopefully see you there? Come and say hi!

 @news-it.bsky.social
Cloudflare、開発者向けデータ基盤「Basin」を発表 – 転送料なしでデータを照会
#Basin #CloudflareBasin #ApacheIceberg #ITニュース
@vyruss.orgSeptember's @PostgresEDI.bsky.social #meetup: tiering cold #PostgreSQL to Apache Iceberg, and @danielroe.dev on #Postgres from Nuxt. Next in #Edinburgh 15 Oct!
#OpenSource #Scotland #Database #Nuxt #UnJs #ColdFront #ApacheIceberg
 @elizabethfue12.bsky.social
S3 Tables now support all Iceberg V3 data types.
Deletion vectors replace positional delete files. Deleting 50k rows from a 2B-row table writes one file instead of thousands. Native variant, nanosecond timestamps, geometry types.
@sriwworldofcoding.bsky.socialThe bigger lesson:
A data lake is not truly useful just because it stores data cheaply.
It becomes valuable when teams can safely update, query, evolve, and recover that data.
@sriwworldofcoding.bsky.socialA data lake gives you cheap, scalable storage.
Apache Iceberg gives that storage memory, structure, time travel, schema evolution, and database-like reliability.
The future of the lakehouse is not more files.
It’s smarter metadata.
@vyruss.orgNext Thursday, Oct 8th, I'm speaking about 🐘🧊 #ColdFront (transparent #PostgreSQL data tiering to Apache Iceberg) at the Iceberg Europe Community #Meetup in #London! Join in person or online.
RSVP: luma.com/ogtqk9eh
 @vyruss.org
Next Wednesday, Oct 7th, I'm speaking at the #London #PostgreSQL #Meetup! I'll present 🐘🧊 #ColdFront: transparent #Postgres data tiering to Apache Iceberg for the modern #Lakehouse.
 @darryl-ruggles.cloud
#DynamoDB #DuckDB #ApacheIceberg #Serverless
There are many different options for databases on AWS and it's great to be able to pick the one that best matches your use case. DynamoDB (DDB) is an example of a highly performant non-relational database which can provide