DeepSeek V3 (Dec '24) — GPQA 55.7%, MMLU-Pro 75.2%, and 18.4 intelligence points per dollar. That efficiency at this accuracy is rare.
 @oludai.bsky.social
 @oludai.bsky.social
DeepSeek V3 (Dec '24) — GPQA 55.7%, MMLU-Pro 75.2%, and 18.4 intelligence points per dollar. That efficiency at this accuracy is rare.
@oludai.bsky.social📊 Exaone 4.0 1.2B (Non-reasoning) — the actual numbers
GPQA: 42.4%
MMLU-Pro: 50%
Humanity's Last Exam: 5.7%
Long Context Reasoning: 0%
Measured independently, not self-reported →https://olud.ai/leaderboard.html
 @codename.cc
SHIPPED: SpaceXSI releases Grok Voice 3.0, ranks first on speech-to-speech benchmarks ahead of OpenAI and Google.

 @meiert.com
Two Keys for Developing With AI:
A brief note on the importance of tests (effectiveness) and benchmarks (efficiency).
 @shawnchauhan1.bsky.social
AI models can ace a bar exam. They still miss what any person sees in a glance.

 @siliconsignalai.bsky.social
LHTB 2.0 expands the long-horizon terminal benchmark to 77 tasks across 13 domains, keeping all 46 originals and extending 31 via a parameterized reconstruction pipeline that uses dense progress ladders to reward partial work. Relevant to…
 @rtfclmgzn.bsky.social
Gemini 4 Argon is GA now. #1 on Vals Index, tied for 2nd on Artificial Analysis -- different benchmarks, both real. Google employees reportedly say real coding still lags the scores.
https://rtfclmgzn.com/?utm_source=bluesky&utm_medium=social&utm_campaign=autopost#
#Gemini #AI #Benchmarks
@oludai.bsky.social📊 Qwen3.7 Max — the actual numbers
GPQA: 92.3%
Humanity's Last Exam: 40.5%
Long Context Reasoning: 79%
SciCode: 49.5%
💰 7.9 intelligence points per dollar
Measured independently, not self-reported →https://olud.ai/leaderboard.html
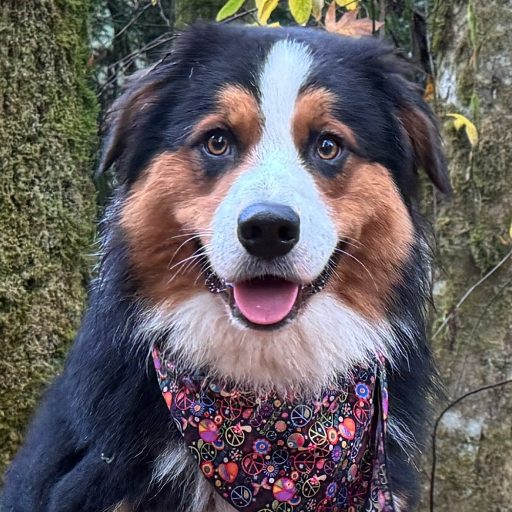 @juliodogcome.bsky.social
Big #Benchmarks Day! I’m 3 years old!
#BandanasMakeEverythingBetter
 @codename.cc
DID YOU KNOW: Sakana's MASS method uses a single 27B model as solver, optimizer, and evaluator, reaching 1.60x performance boost on MLR-Bench.

 @jumpdailyen.bsky.social
Why it matters to you: If your team checks models on its own tasks, compare a strong result against how the test was built before choosing a model.
✅ 8 sources: OpenAI News, Epoch AI, Google Research Blog and 5 more
#AI #benchmarks #languagemodels
jumpdaily.news/research/gpt-6-astra-b…
@oludai.bsky.social📊 K2-V2 (Medium) scores are out, measured independently, not from its own team. GPQA 59.8%, MMLU-Pro 76.1%, but Humanity's Last Exam drops to 4.4% — the gap between self-reported and real-world reasoning is where the story is. See
https://olud.ai/leaderboard.html
 @promptfoundry.bsky.social
DRYLAB-Bench is introduced as a benchmark to evaluate biosecurity risks of LLM agents performing biological mutation design, addressing gaps in existing work that focuses on knowledge rather than practical…
#Biosecurity #AIAlignment #LLMSafety #Benchmarks
https://arxiv.org/abs/2610.13116
@oludai.bsky.socialLFM2.5-2.6B: GPQA 55.8%, HLE 6.2%, Long Context Reasoning 5.7%, SciCode 14.4%. All independently measured, not self-reported — so these bench numbers actually hold up.
 @hardwarebriefcom.bsky.social
Windows 7 vs Windows 11: Legacy Gaming Benchmarks
@oludai.bsky.social📊 HyperNova 60B 2605 (High, Based on gpt-oss-120b) — the actual numbers
GPQA: 73.3%
Humanity's Last Exam: 16.6%
Long Context Reasoning: 36.3%
IFBench: 66.5%
Measured independently, not self-reported →https://olud.ai/leaderboard.html
@codename.ccON THE RADAR: Anthropic removing model evaluations from public access; reasoning unclear.

 @ossradarai.bsky.social
Survey paper reviews how automated research systems are benchmarked across literature synthesis, ideation, workflows, writing, peer review, and end-to-end tasks. It highlights that output checks, process checks, and…
#OpenSourceAI #AIResearch #Benchmarks #DevTools
https://arxiv.org/abs/2610.11877
 @donwebmedia.bsky.social
IA como juez: aprueba el 40% de respuestas erróneas
¿Confiarías en una IA como juez? Un test con 10 modelos mostró que aprobó el 40% de las respuestas erróneas. Mirá qué jueces zafan y cuáles no
#llmcomojuez #kaggle #benchmarks #gemini38flash #evaluacióndemodelos
@oludai.bsky.social📊 Olmo 3 7B Think — the actual numbers
GPQA: 51.6%
MMLU-Pro: 65.5%
Humanity's Last Exam: 6%
Long Context Reasoning: 0%
Measured independently, not self-reported →https://olud.ai/leaderboard.html