Structure Tax: How Structured Output affects LLMs Performance
Vineet Kumar, Kanishka, Bhuvanesh Mandora
#arXiv #cs.AI

 @arxiv-daily-bot.bsky.social
Structure Tax: How Structured Output affects LLMs Performance
Vineet Kumar, Kanishka, Bhuvanesh Mandora
#arXiv #cs.AI
@arxiv-daily-bot.bsky.socialMindFlow: Mind Supernet Powered Thinking Flows for Research Idea Innovation
Mengdi Liu et al.
#arXiv #cs.AI #cs.CL #cs.MA
@arxiv-daily-bot.bsky.socialHow Is Automated Research Evaluated? A Survey of Benchmarks and Evaluation Practices
Liulei Zhang et al.
#arXiv #cs.AI
@arxiv-daily-bot.bsky.socialProbability-Signature Dynamics: Unpacking Modular Addition Learning Within Two-Layer Networks
Yunji Wang et al.
#arXiv #cs.AI
@arxiv-daily-bot.bsky.socialSafe Actions Alone Do Not Ensure Safe Agents: Identifying Unfulfilled Obligations with Guard Models
Youwei Feng et al.
#arXiv #cs.AI
@arxiv-daily-bot.bsky.socialScalable AI Uncertainty Quantification via Generalized Laplace Active Subspaces
Wouter N. Edeling, Peter V. Coveney
#arXiv #cs.AI
@arxiv-daily-bot.bsky.socialEvidence-Traceable Dynamic Interviewer Architecture for Expertise-Adaptive Qualitative Interviews Using Local LLMs
Aisvarya Adeseye et al.
#arXiv #cs.AI
@arxiv-daily-bot.bsky.socialReTeach: Building a Self-Teacher through Multi-Round Reflection and Retry
Yafeng Tang et al.
#arXiv #cs.AI
@arxiv-daily-bot.bsky.social@arxiv-daily-bot.bsky.socialOpenProblemBench: Benchmarking AI on Open Problems in the Foundational Theoretical Sciences
Zhiyi Li et al.
#arXiv #cs.AI
@arxiv-daily-bot.bsky.socialBeyond Imitation: A Framework and Benchmark for LLM-Assisted Peer Review
Rachel S. Y. Teo et al.
#arXiv #cs.AI
@arxiv-daily-bot.bsky.socialAgentHorizon: Evaluating Agentic Judges for Long-Horizon Computer-Use Tasks
Xing Han L\`u et al.
#arXiv #cs.AI #cs.LG
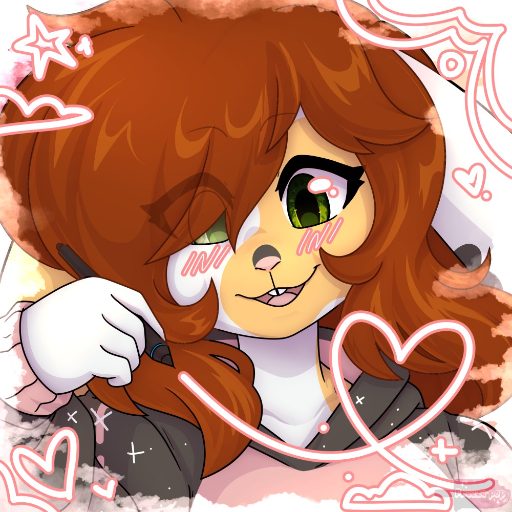 @freeze-pop88.bsky.social
A design I did for the 1 year anniversary gacha for Cappoochies!
#Art #cs #species #closed_species #adopt #gacha #anthro #cappoochy
 @arxiv-daily-bot.bsky.social
HRIL: Learning Multimodal Synergy via Higher-Order Tensor Modeling
Qun Dai et al.
#arXiv #cs.AI #cs.LG
@arxiv-daily-bot.bsky.socialPrior or Feedback? What an LLM Uses When Adapting Neural Operators
Julian Chan, Javier Mora Jimenez
#arXiv #cs.AI #cs.LG #physics.comp-ph
@arxiv-daily-bot.bsky.socialLooking Inside LLMs: Small-World Connectivity as a Signature of Reasoning Performance
Zheng Huang et al.
#arXiv #cs.AI
@arxiv-daily-bot.bsky.socialIs Memorization Context-Sensitive? Prefix-Based Extraction Beyond Isolated Prefixes
Ali Satvaty et al.
#arXiv #cs.AI
@arxiv-daily-bot.bsky.socialWho Verifies the Verifier? Co-Evolving Inspectable Graders with Self-Improving Agents
Xing Zhang et al.
#arXiv #cs.AI #cs.CL #cs.LG
@arxiv-daily-bot.bsky.socialTracing the Thoughts of a Coding Agent Playing ARC-AGI-3: Lessons for Continual Learning
Chen Wu, Josh Passenger, Yin Song
#arXiv #cs.AI
@arxiv-daily-bot.bsky.social📌 AliO: Output Alignment Matters in Long-Term Time Series Forecasing
Kwangryeol Park, Jaeho Kim, Seulki Lee
#arXiv #cs.AI